The Challenge of On-Device AI Assistants
Building an AI assistant that operates entirely on-device, without relying on cloud calls, presents a unique set of challenges. FamiliaSync, an offline-first family organizer, faces this constraint head-on. Every query must be processed locally, ensuring user data remains encrypted and private on their own devices. This strict requirement means the assistant cannot simply offload complex natural language understanding or intent recognition to external servers. Historically, many such assistants have relied on hand-written rules or pattern matching to interpret user commands. While effective for a defined set of known intents, this approach quickly becomes brittle and unmanageable as the range of user requests expands. It requires constant manual updates and struggles with variations in phrasing or novel queries.
FamiliaSync's previous system employed this manual approach. When a user made a request, a hand-written intent router would attempt to decipher their meaning. If the request matched a predefined pattern, it would be routed to the appropriate function. For more open-ended requests, it would be passed to Needle 2, an on-device model designed for reasoning. However, the limitations of a purely rule-based system are significant. It lacks flexibility and the ability to gracefully handle ambiguity or queries outside its programmed scope. This often leads to frustrating user experiences where the assistant either misunderstands the request or simply fails to respond.
The team at FamiliaSync recognized that a more robust and adaptable solution was needed. The goal was to create an on-device assistant that not only understood a wide range of commands but could also intelligently admit when it didn't understand, rather than guessing or providing an incorrect response. This is particularly critical for a privacy-focused application where user trust is paramount. Any misinterpretation or unexpected behavior could erode that trust. The fundamental problem was how to improve the initial interpretation layer without compromising the on-device constraint.
Introducing the On-Device Intent Classifier
The solution FamiliaSync implemented was to replace the brittle, hand-written intent router with a small, on-device classifier. This classifier is trained directly on the user's device, meaning no training data ever leaves the user's control. This approach marks a significant shift from traditional methods. Instead of a rigid set of `if-then` rules, the assistant now uses a machine learning model that learns to map natural language utterances to specific intents. This model is trained on a carefully curated corpus of examples, not generated in bulk. The current training corpus supports 105 distinct intents, each backed by approximately 2,400 example utterances. These utterances are designed to carry the necessary slots (like dates, times, or names) that real commands require, ensuring the model learns to recognize not just the intent but also the critical parameters within the command.
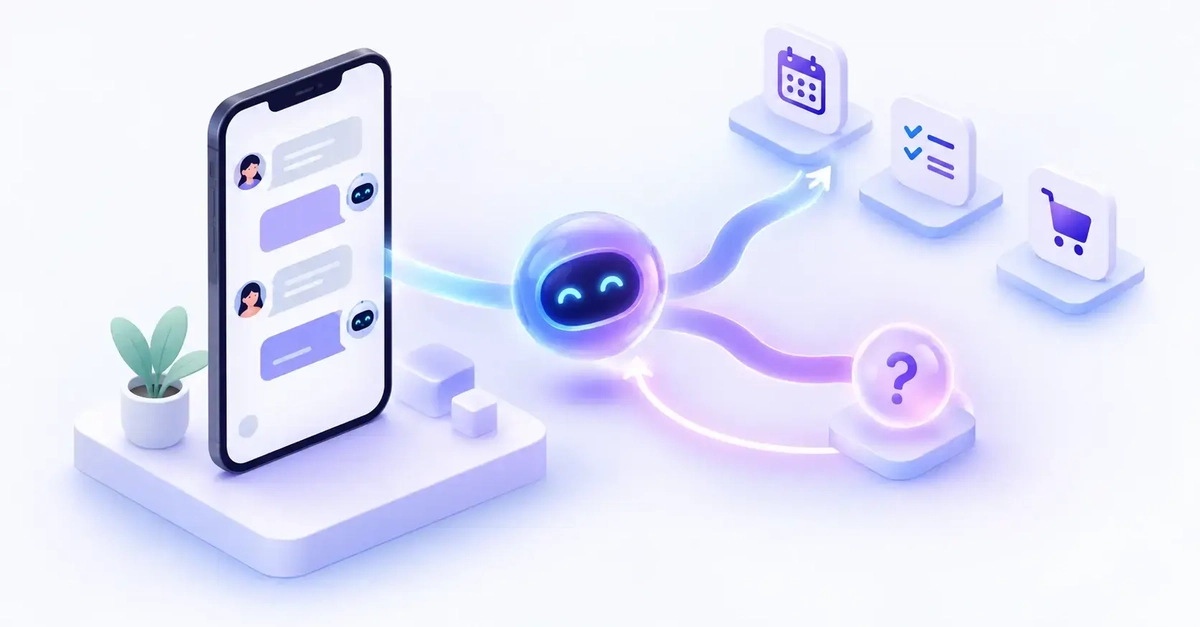
The pipeline's core spirit remains the same: text input is analyzed to determine the user's intent. If the intent is recognized and can be handled by a specific tool (like setting a reminder or adding an event), it's routed accordingly. However, the crucial innovation lies in how unknown or complex intents are handled. The classifier's output provides a confidence score for each potential intent. If the highest confidence score for any intent falls below a certain threshold, the assistant can now confidently say, "I don't know." This is a deliberate and important design choice. Instead of attempting to guess or provide a potentially incorrect answer, the assistant defers, prioritizing accuracy and user trust over attempting to handle every single query, regardless of certainty.
The Benefits of Admitting Ignorance
Teaching an AI assistant to say "I don't know" might seem counterintuitive, but it's a vital step towards creating more reliable and trustworthy AI systems, especially in privacy-sensitive contexts. For FamiliaSync, this capability offers several key advantages:
- Enhanced Privacy: By keeping all processing on-device and avoiding cloud calls, user data remains secure and private. The classifier itself is trained and runs locally, eliminating the risk of sensitive query data being transmitted or stored externally.
- Improved User Experience: Instead of frustrating users with incorrect interpretations or nonsensical responses, the assistant can gracefully acknowledge its limitations. This manages user expectations and reduces the likelihood of errors that could impact their data or tasks.
- Increased Robustness: A classifier, even a small one, is generally more robust to variations in language than a rigid set of hand-written rules. It can better handle synonyms, slightly different phrasing, and grammatical errors, leading to a higher success rate for understood intents.
- Reduced Maintenance Overhead: Training and managing a machine learning model, while requiring expertise, can be more scalable than manually updating thousands of rules. The focus shifts from brittle rule creation to curating a high-quality training dataset and refining the model.
- Foundation for Future Growth: This approach provides a solid foundation for future expansion. As FamiliaSync identifies new intents or user needs, they can be incorporated into the training data, and the model can be retrained, allowing the assistant to learn and adapt over time.
The decision to replace a manual router with a trained classifier is a subtle but powerful upgrade. It moves the assistant from a purely deterministic system to one that incorporates probabilistic reasoning, a hallmark of modern AI. When the model's confidence is low, it signals a boundary of its current understanding. This boundary is not a failure but an informative state that the system can communicate to the user. This is akin to a human assistant admitting they need to look something up rather than fabricating an answer.
Broader Implications for On-Device AI
FamiliaSync's approach highlights a growing trend in the development of on-device AI. As concerns over data privacy and security intensify, the ability to perform sophisticated AI tasks locally is becoming increasingly valuable. This move away from cloud-dependent AI is not just a niche requirement for privacy-focused apps; it's a broader industry shift. Edge AI, or on-device AI, enables lower latency, offline functionality, and reduced data transmission costs. However, deploying capable AI models on resource-constrained devices requires careful optimization in terms of model size, computational efficiency, and power consumption.
The success of FamiliaSync's classifier hinges on several factors: the quality and diversity of the training data, the choice of classification model architecture, and the threshold set for admitting ignorance. A model trained on a limited or biased dataset will inevitably perform poorly. Similarly, if the confidence threshold is set too high, the assistant will frequently say "I don't know," defeating its purpose. Conversely, a threshold set too low risks returning to the problem of misinterpretation. Finding this balance is key.
What remains to be seen is how users will react to an AI that openly admits its limitations. While trust and privacy are paramount, users also expect assistants to be capable and helpful. A system that says "I don't know" too often, even if accurate, might still be perceived as less useful than one that occasionally makes a minor error but gets things done. The ongoing challenge for developers in this space will be to continually improve the accuracy and scope of on-device models, thereby shrinking the situations where "I don't know" is the appropriate response, while still maintaining the core principles of privacy and local processing.
FamiliaSync's implementation is a pragmatic and privacy-conscious solution that addresses a core limitation of on-device AI assistants. By embracing the "I don't know" response, they are building a more honest and trustworthy user experience, demonstrating that sometimes, the smartest response is to admit you don't have the answer.