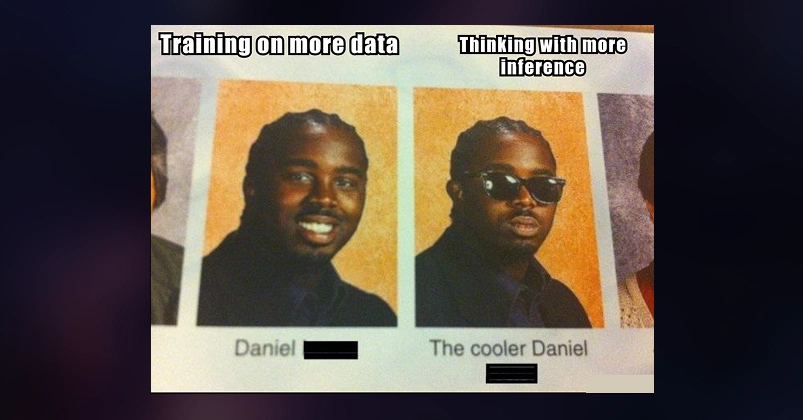
The Shifting Landscape of AI Scaling
The rapid advancement of Artificial Intelligence is often attributed to scaling. Initially, this meant feeding models more data and more computational power. However, the definition of AI scaling has evolved significantly. It's no longer a one-dimensional pursuit. Today, we understand AI scaling as a multi-faceted approach encompassing three distinct, yet interconnected, laws: Pre-training Scaling, Architectural Scaling, and Reasoning Scaling.
Understanding these three laws is crucial for anyone building, deploying, or even just observing the AI landscape. They represent the fundamental drivers behind the increasingly sophisticated capabilities we see in AI systems today.
Pre-training Scaling: The Foundation of Knowledge
The first and perhaps most intuitive scaling law is Pre-training Scaling. This law describes the process of improving AI models by increasing the sheer volume of data they are trained on and the computational resources dedicated to that training. Think of it as a student cramming for a comprehensive general knowledge exam: the more they study, the more facts they absorb, and the broader their understanding becomes.
Early successes in natural language processing, like large language models (LLMs), were heavily reliant on this principle. By exposing models to massive datasets scraped from the internet, researchers found that performance across a wide range of tasks improved predictably. As datasets grew and training compute budgets ballooned, models became more adept at tasks like text generation, translation, and question answering. This approach is foundational; without a vast base of knowledge, more advanced scaling methods would have limited impact.
However, this approach has limitations. The cost of pre-training is astronomical, and the gains from simply adding more data or compute begin to diminish beyond certain thresholds. Furthermore, simply absorbing information doesn't guarantee the ability to use it effectively or reason about it.
Architectural Scaling: Building Smarter Models
The second scaling law, Architectural Scaling, addresses the structure and design of AI models themselves. While pre-training focuses on the 'what' (data and compute), architectural scaling focuses on the 'how' (the model's internal mechanisms). This involves developing more efficient, capable, and specialized model architectures.
Consider it like designing a more sophisticated brain. Instead of just filling a student's head with facts, architectural scaling is about optimizing the neural pathways and cognitive structures that allow for better information processing, pattern recognition, and learning. Innovations like the Transformer architecture, with its self-attention mechanisms, dramatically improved AI's ability to handle sequential data and long-range dependencies, leading to breakthroughs in NLP.
This law also encompasses techniques like:
- Model Parallelism and Distributed Training: Techniques that allow massive models to be trained across multiple devices and processors efficiently.
- Sparse Models and Mixture-of-Experts (MoE): Architectures that use only a fraction of their parameters for any given input, making them more computationally efficient for their size.
- Novel Attention Mechanisms: Developing alternatives to standard self-attention that are more computationally tractable for very long sequences.
Architectural innovations allow models to learn more effectively from the same amount of data, or to tackle problems that were previously intractable due to computational constraints. It's about making the AI smarter in its internal workings, not just in the volume of its knowledge.
Reasoning Scaling: Thinking More, Not Just Knowing More
The third and arguably most advanced scaling law is Reasoning Scaling. This law moves beyond mere knowledge acquisition and pattern recognition to focus on the AI's ability to perform complex cognitive tasks, infer, plan, and engage in multi-step reasoning. This is where AI begins to 'think' more critically.
If pre-training is about memorization and architectural scaling is about efficient processing, reasoning scaling is about problem-solving and understanding. It’s akin to a student not just knowing historical facts, but being able to analyze causes and effects, predict outcomes, and formulate arguments. This involves techniques like:
- Chain-of-Thought (CoT) Prompting: Encouraging models to break down complex problems into intermediate steps, mimicking human thought processes.
- Self-Correction and Reflection: Enabling models to review their own outputs, identify errors, and refine their answers.
- Tool Use and Augmentation: Allowing AI models to interact with external tools (like calculators, search engines, or code interpreters) to enhance their reasoning capabilities.
- Improved Fine-tuning and Alignment: Techniques that steer model behavior towards more logical and coherent outputs, aligning them with human reasoning patterns.
Reasoning scaling is critical for applications requiring complex decision-making, strategic planning, or deep understanding of nuanced situations. It’s the frontier where AI moves from being a sophisticated information retriever to a capable problem-solver. The surprising detail here is how much performance gains can be unlocked by simply guiding the model's internal thought process, often without requiring additional training data or fundamental architectural changes.
Interplay and Future Directions
These three scaling laws are not independent. Advances in one area often unlock potential in others. For instance, more efficient architectures (architectural scaling) can enable larger models to be trained more effectively (pre-training scaling) or allow for more complex reasoning steps to be computed (reasoning scaling). Similarly, better reasoning capabilities might allow AI to identify and request more relevant data for pre-training or suggest improvements to its own architecture.
The future of AI scaling will likely involve a more integrated approach, optimizing all three laws in tandem. We can expect continued research into novel architectures, more efficient training methodologies, and advanced techniques for imbuing AI with robust reasoning abilities. The race is on to build AI that not only knows more but also thinks more effectively and efficiently.