The Imperative of Prompt Optimization
Large Language Models (LLMs) have rapidly evolved from novelties to indispensable tools across industries. However, their raw potential is often bottlenecked by the quality of the input they receive. Simply put, a poorly crafted prompt yields a poor response. This is where prompt optimization, a core tenet of prompt engineering, becomes critical. It’s not about finding the perfect, single prompt, but rather a systematic approach to refining inputs to elicit the desired outputs consistently. The goal is to move beyond generic answers and achieve specific, accurate, and contextually relevant results from models like GPT-3, GPT-4, Claude, and others.
Think of interacting with an LLM like briefing a highly intelligent but literal-minded junior associate. If you give vague instructions, you’ll get vague work. If you provide clear, detailed context and examples, you’ll get precisely what you asked for. Prompt optimization is the art and science of crafting those clear, detailed instructions. It’s an iterative process that involves understanding the model’s nuances, the specific task at hand, and the desired outcome.
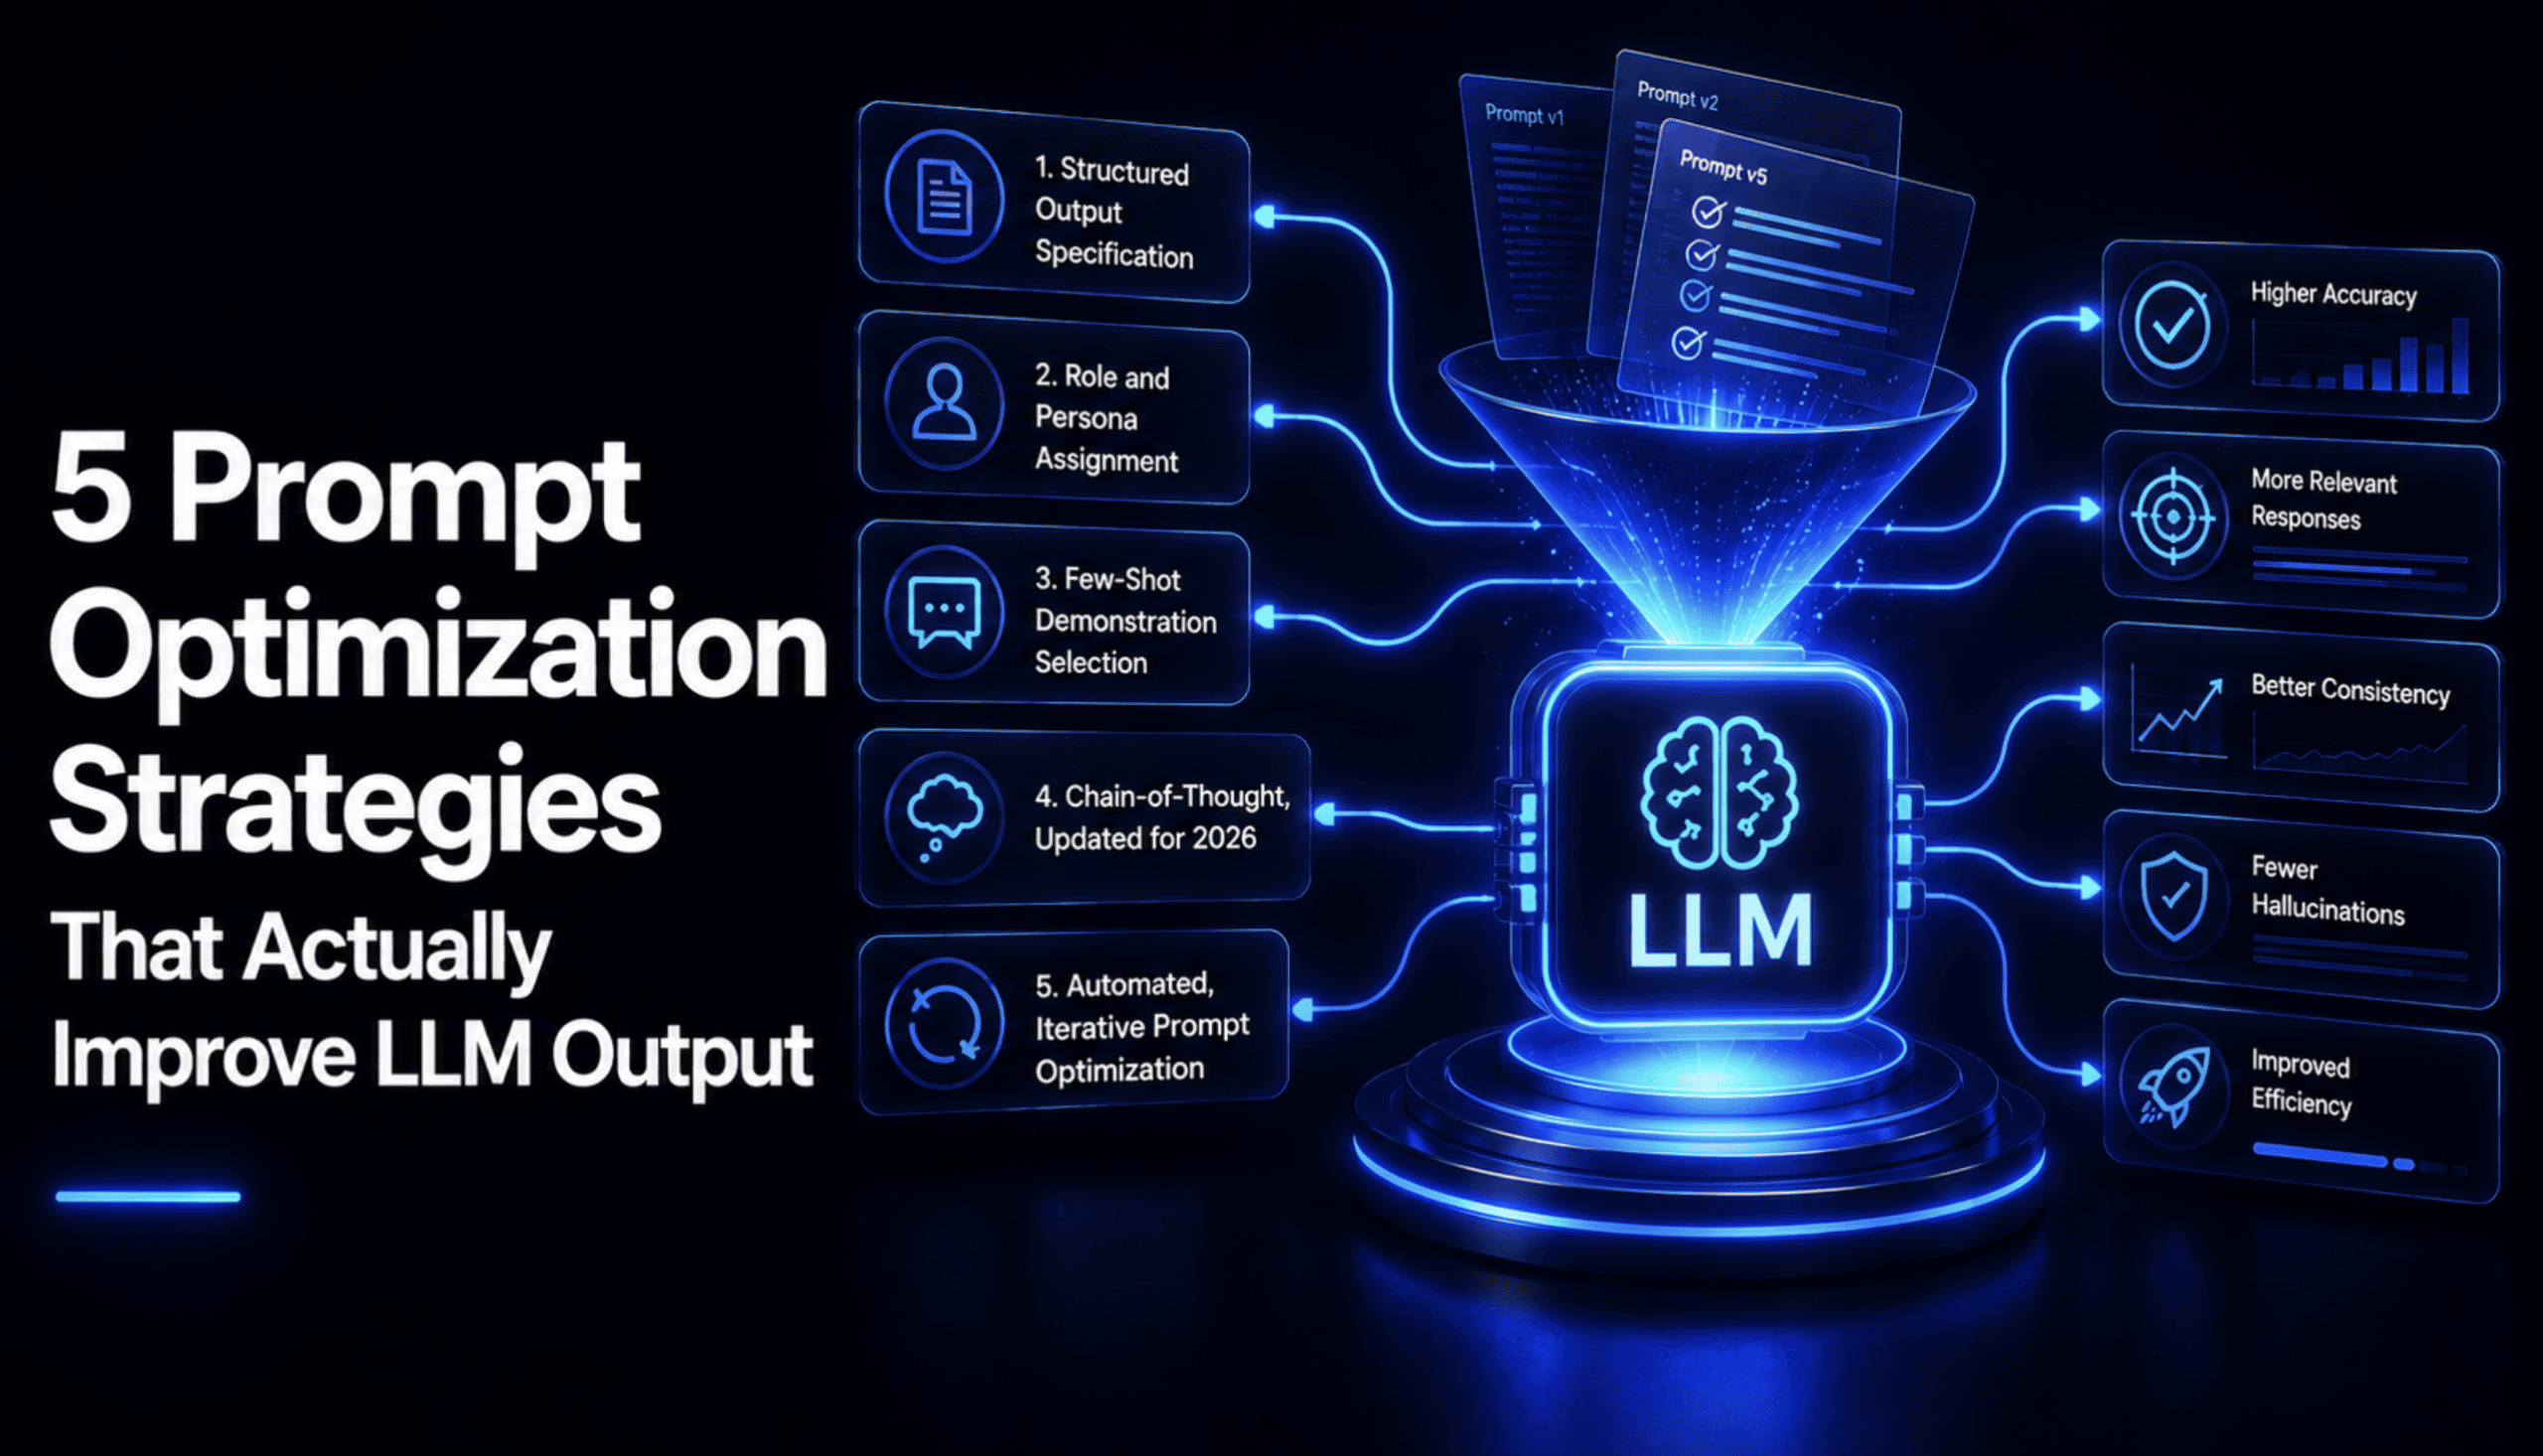
This article explores five fundamental strategies that have proven effective in improving LLM output quality. These techniques range from providing context and examples to structuring the model’s reasoning process and output format.
1. Few-Shot Prompting: Learning from Examples
One of the most powerful techniques for guiding LLMs is few-shot prompting. Instead of just asking a question or providing an instruction, you include a few examples of the desired input-output pairs within the prompt itself. This provides the model with concrete demonstrations of what you expect, allowing it to infer the underlying pattern or task without explicit rule-based programming.
For instance, if you want an LLM to classify customer feedback into positive, negative, or neutral sentiment, a zero-shot prompt might be: "Classify the sentiment of the following feedback: 'The app is slow and crashes often.'" An LLM might struggle with nuances or less common phrasing. A few-shot prompt, however, would look like this:
Feedback: 'I love the new interface, it's so intuitive!'
Sentiment: Positive

Feedback: 'The update broke my existing settings.'
Sentiment: Negative

Feedback: 'It works as expected, no major issues.'
Sentiment: Neutral

Feedback: 'The app is slow and crashes often.'
Sentiment:
By providing these examples, the LLM grasps the desired classification scheme much more effectively. The number of shots (examples) can vary. Too few might not provide enough context, while too many can make the prompt excessively long and potentially dilute the model’s focus or exceed context window limits. The key is to select representative examples that cover the common cases and edge cases you anticipate.
2. Chain-of-Thought (CoT) Prompting: Deconstructing Reasoning
Many complex problems require a series of logical steps to solve. LLMs, while powerful, can sometimes jump to conclusions or make errors when faced with multi-step reasoning. Chain-of-Thought (CoT) prompting addresses this by encouraging the model to articulate its reasoning process step-by-step before arriving at a final answer. This mimics human problem-solving, where we break down a challenge into smaller, manageable parts.
CoT prompting can be implemented in a few-shot manner. You provide examples where the desired output includes not just the final answer, but also the intermediate reasoning steps. For example, when asking a math word problem:
Q: Roger has 5 tennis balls. He buys 2 more cans of tennis balls. Each can has 3 tennis balls. How many tennis balls does he have now?
A: Roger started with 5 balls. 2 cans of 3 balls each is 2 * 3 = 6 balls. So he has 5 + 6 = 11 balls. The answer is 11.

Q: The cafeteria had 23 apples. If they used 20 to make lunch and bought 6 more, how many apples do they have?
A: The cafeteria started with 23 apples. They used 20, so they had 23 - 20 = 3 apples left. Then they bought 6 more. So they have 3 + 6 = 9 apples. The answer is 9.

Q: [Your complex question here]
A:
By explicitly showing the model how to 'think out loud,' CoT prompting significantly improves accuracy on tasks requiring logical deduction, arithmetic, or symbolic manipulation. It makes the model's decision-making process more transparent and verifiable, which is invaluable for debugging and understanding errors.
3. Structured Output: Enforcing Format and Consistency
LLMs can be notoriously verbose or unstructured in their responses. For applications that require predictable data formats, such as JSON, XML, or markdown tables, directly asking for them can sometimes yield inconsistent results. Structured output prompting involves explicitly defining the desired output schema within the prompt.
This can be as simple as appending instructions like "Respond in JSON format" or "Provide the answer as a markdown table." More advanced techniques involve providing a template or schema definition that the LLM must adhere to. For instance, if you need to extract specific entities from a text:
Extract the company name, CEO, and stock ticker from the following text. Respond in JSON format with keys 'company', 'ceo', and 'ticker'.

Text: "TechCorp announced today that Jane Doe will be its new CEO, with the company's stock trading under the symbol TCOR."

JSON:
{
  "company": "TechCorp",
  "ceo": "Jane Doe",
  "ticker": "TCOR"
}

Text: "Global Solutions Inc. has appointed John Smith as its new Chief Executive Officer. The company is listed on the NASDAQ as GSI."

JSON:
This strategy is crucial for integrating LLM outputs into downstream applications, ensuring that the data is machine-readable and consistently formatted, reducing the need for extensive post-processing or error handling.
4. Role-Playing: Setting the Persona and Context
LLMs can adopt different personas based on instructions. Role-playing prompts instruct the model to act as a specific character, expert, or entity. This is highly effective for tasks where a particular tone, perspective, or level of expertise is required.
For example, instead of asking "Explain quantum physics," you could prompt: "You are a renowned physics professor explaining quantum entanglement to a bright high school student. Use analogies and avoid overly technical jargon." This instruction primes the model to adopt a specific pedagogical style and adjust its vocabulary accordingly. Similarly, asking an LLM to "Act as a senior software engineer reviewing code" will likely yield more critical and detailed feedback than a general request to "Review this code."